rednote, dots Foundation Model Team
Research Intern
My research focuses on multimodal large language models for video understanding and spatio-temporal reasoning.
I am a PhD student at Westlake University, advised by Peidong Liu. I work on multimodal data construction, SFT/RL post-training, and evidence-grounded evaluation, with applications in temporal grounding and embodied captioning.
Research Intern
Research Intern · Mentored by Ke Wang and Xiongcai Luo
Research Intern, LLM Strategy · Mentored by Xiangtai Li
B.S. in Spatial Information and Digital Technology
Research direction
Connecting vision, language, and 3D scene representations to improve spatial understanding and reasoning about the physical world.
Observe
Temporal grounding and embodied captioning.
Interpret
Connecting visual evidence, language, and 3D scene representations.
Learn
Data construction, SFT/RL, and evidence-grounded evaluation.
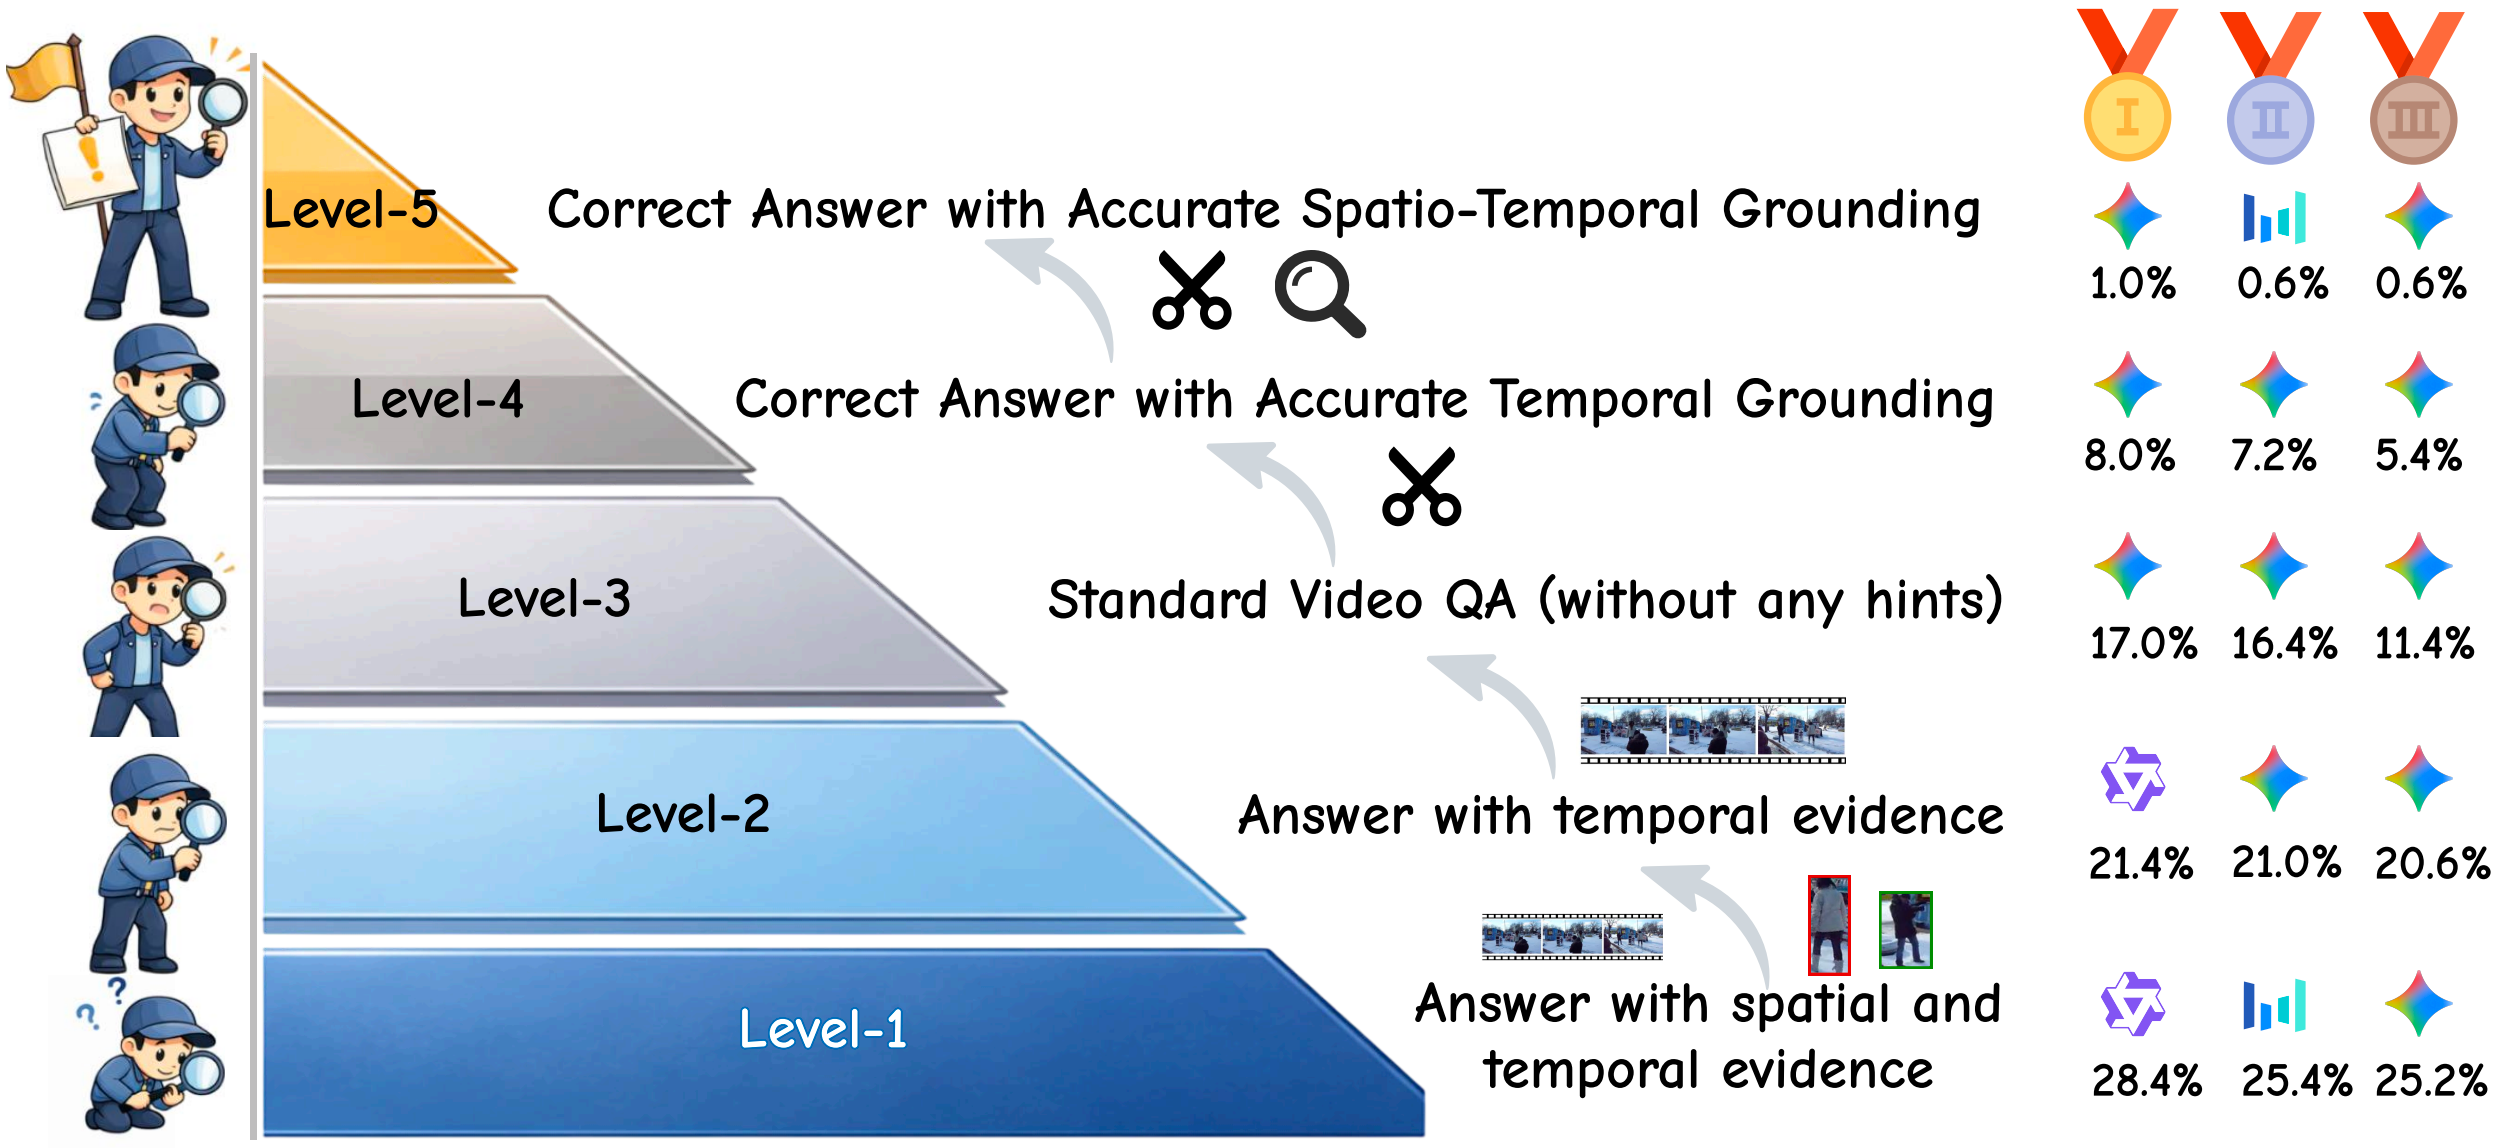
VideoZeroBench was released with code and data for evidence-grounded long-video evaluation.
Any 3D Scene is Worth 1K Tokens was released on arXiv.
Two advised-student papers were accepted to ECCV 2026.
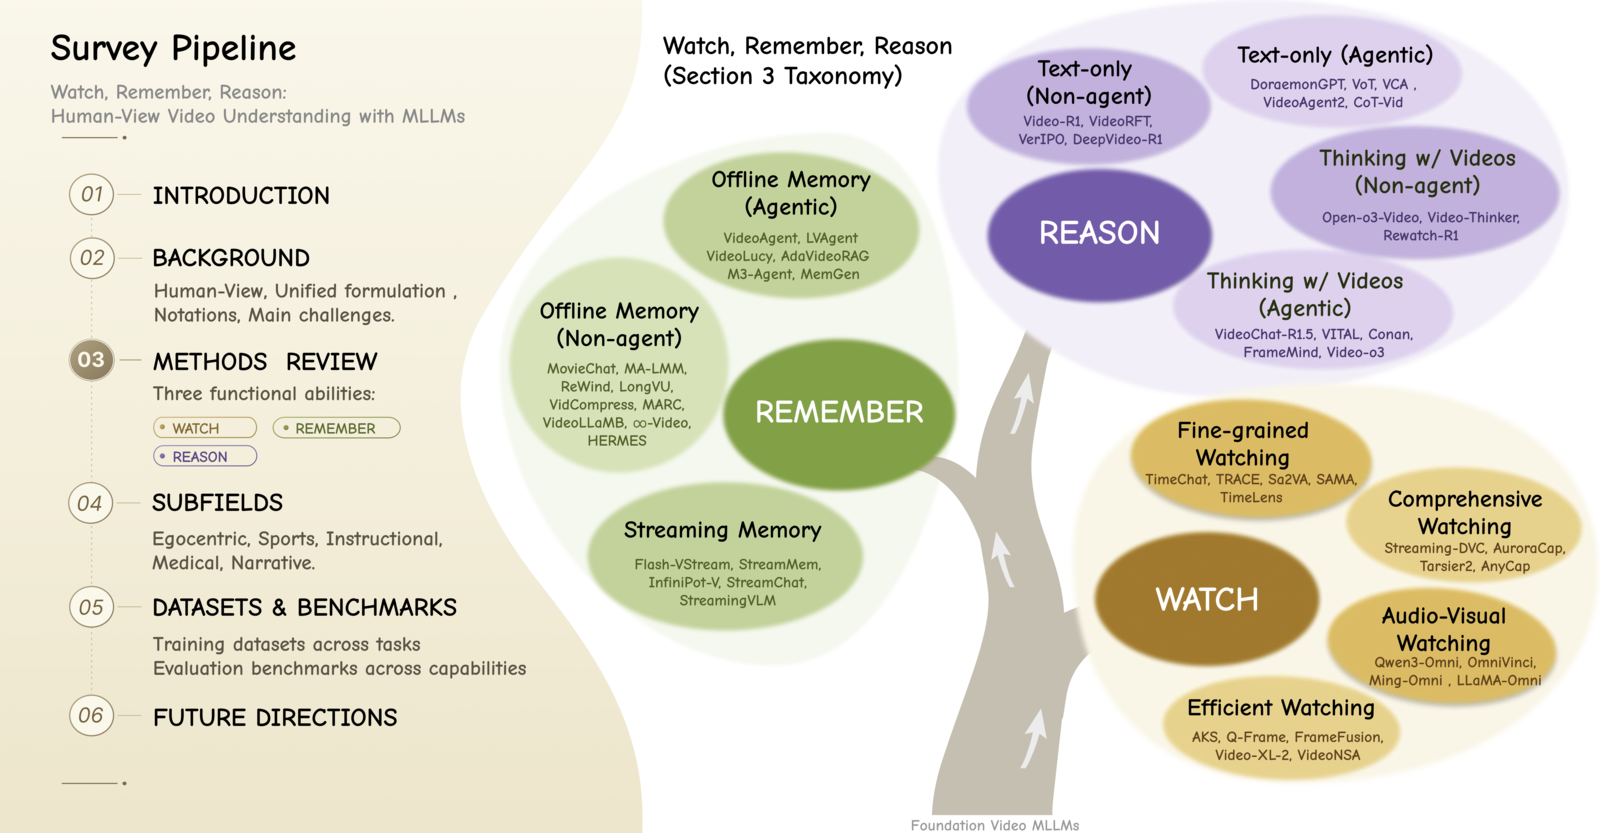
Watch, Remember, Reason was released on arXiv.
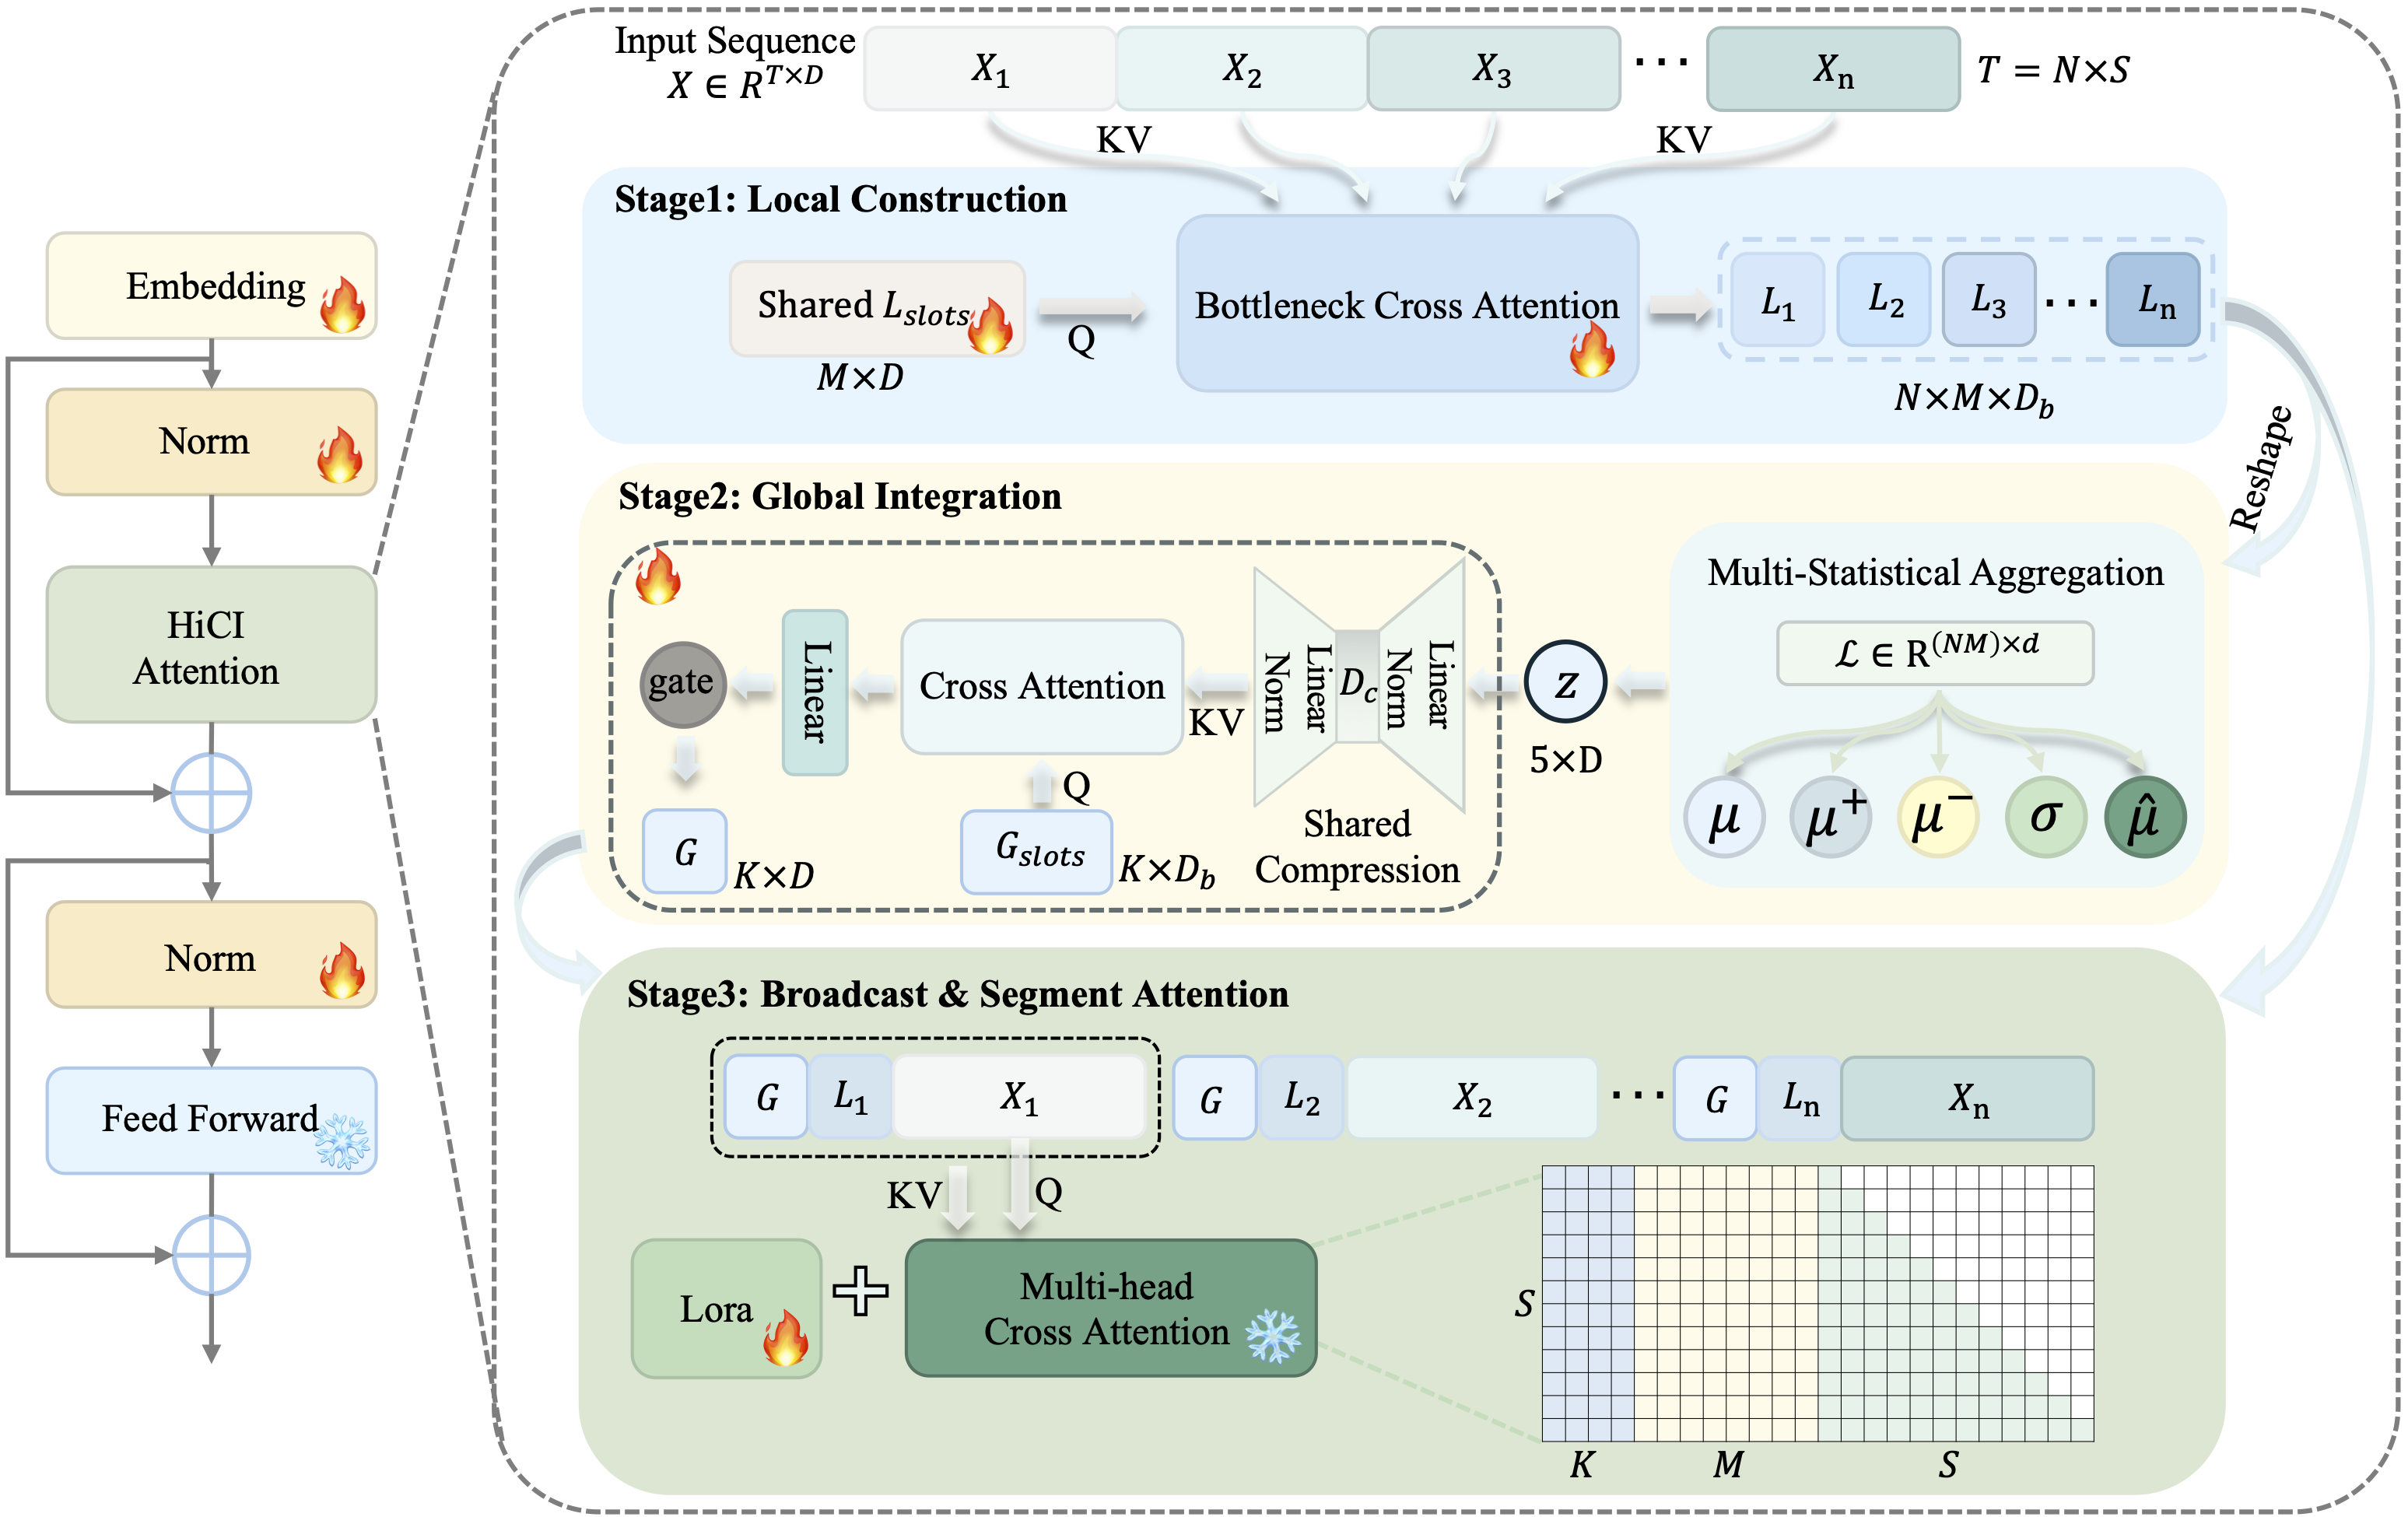
HiCI was accepted to ICML 2026.
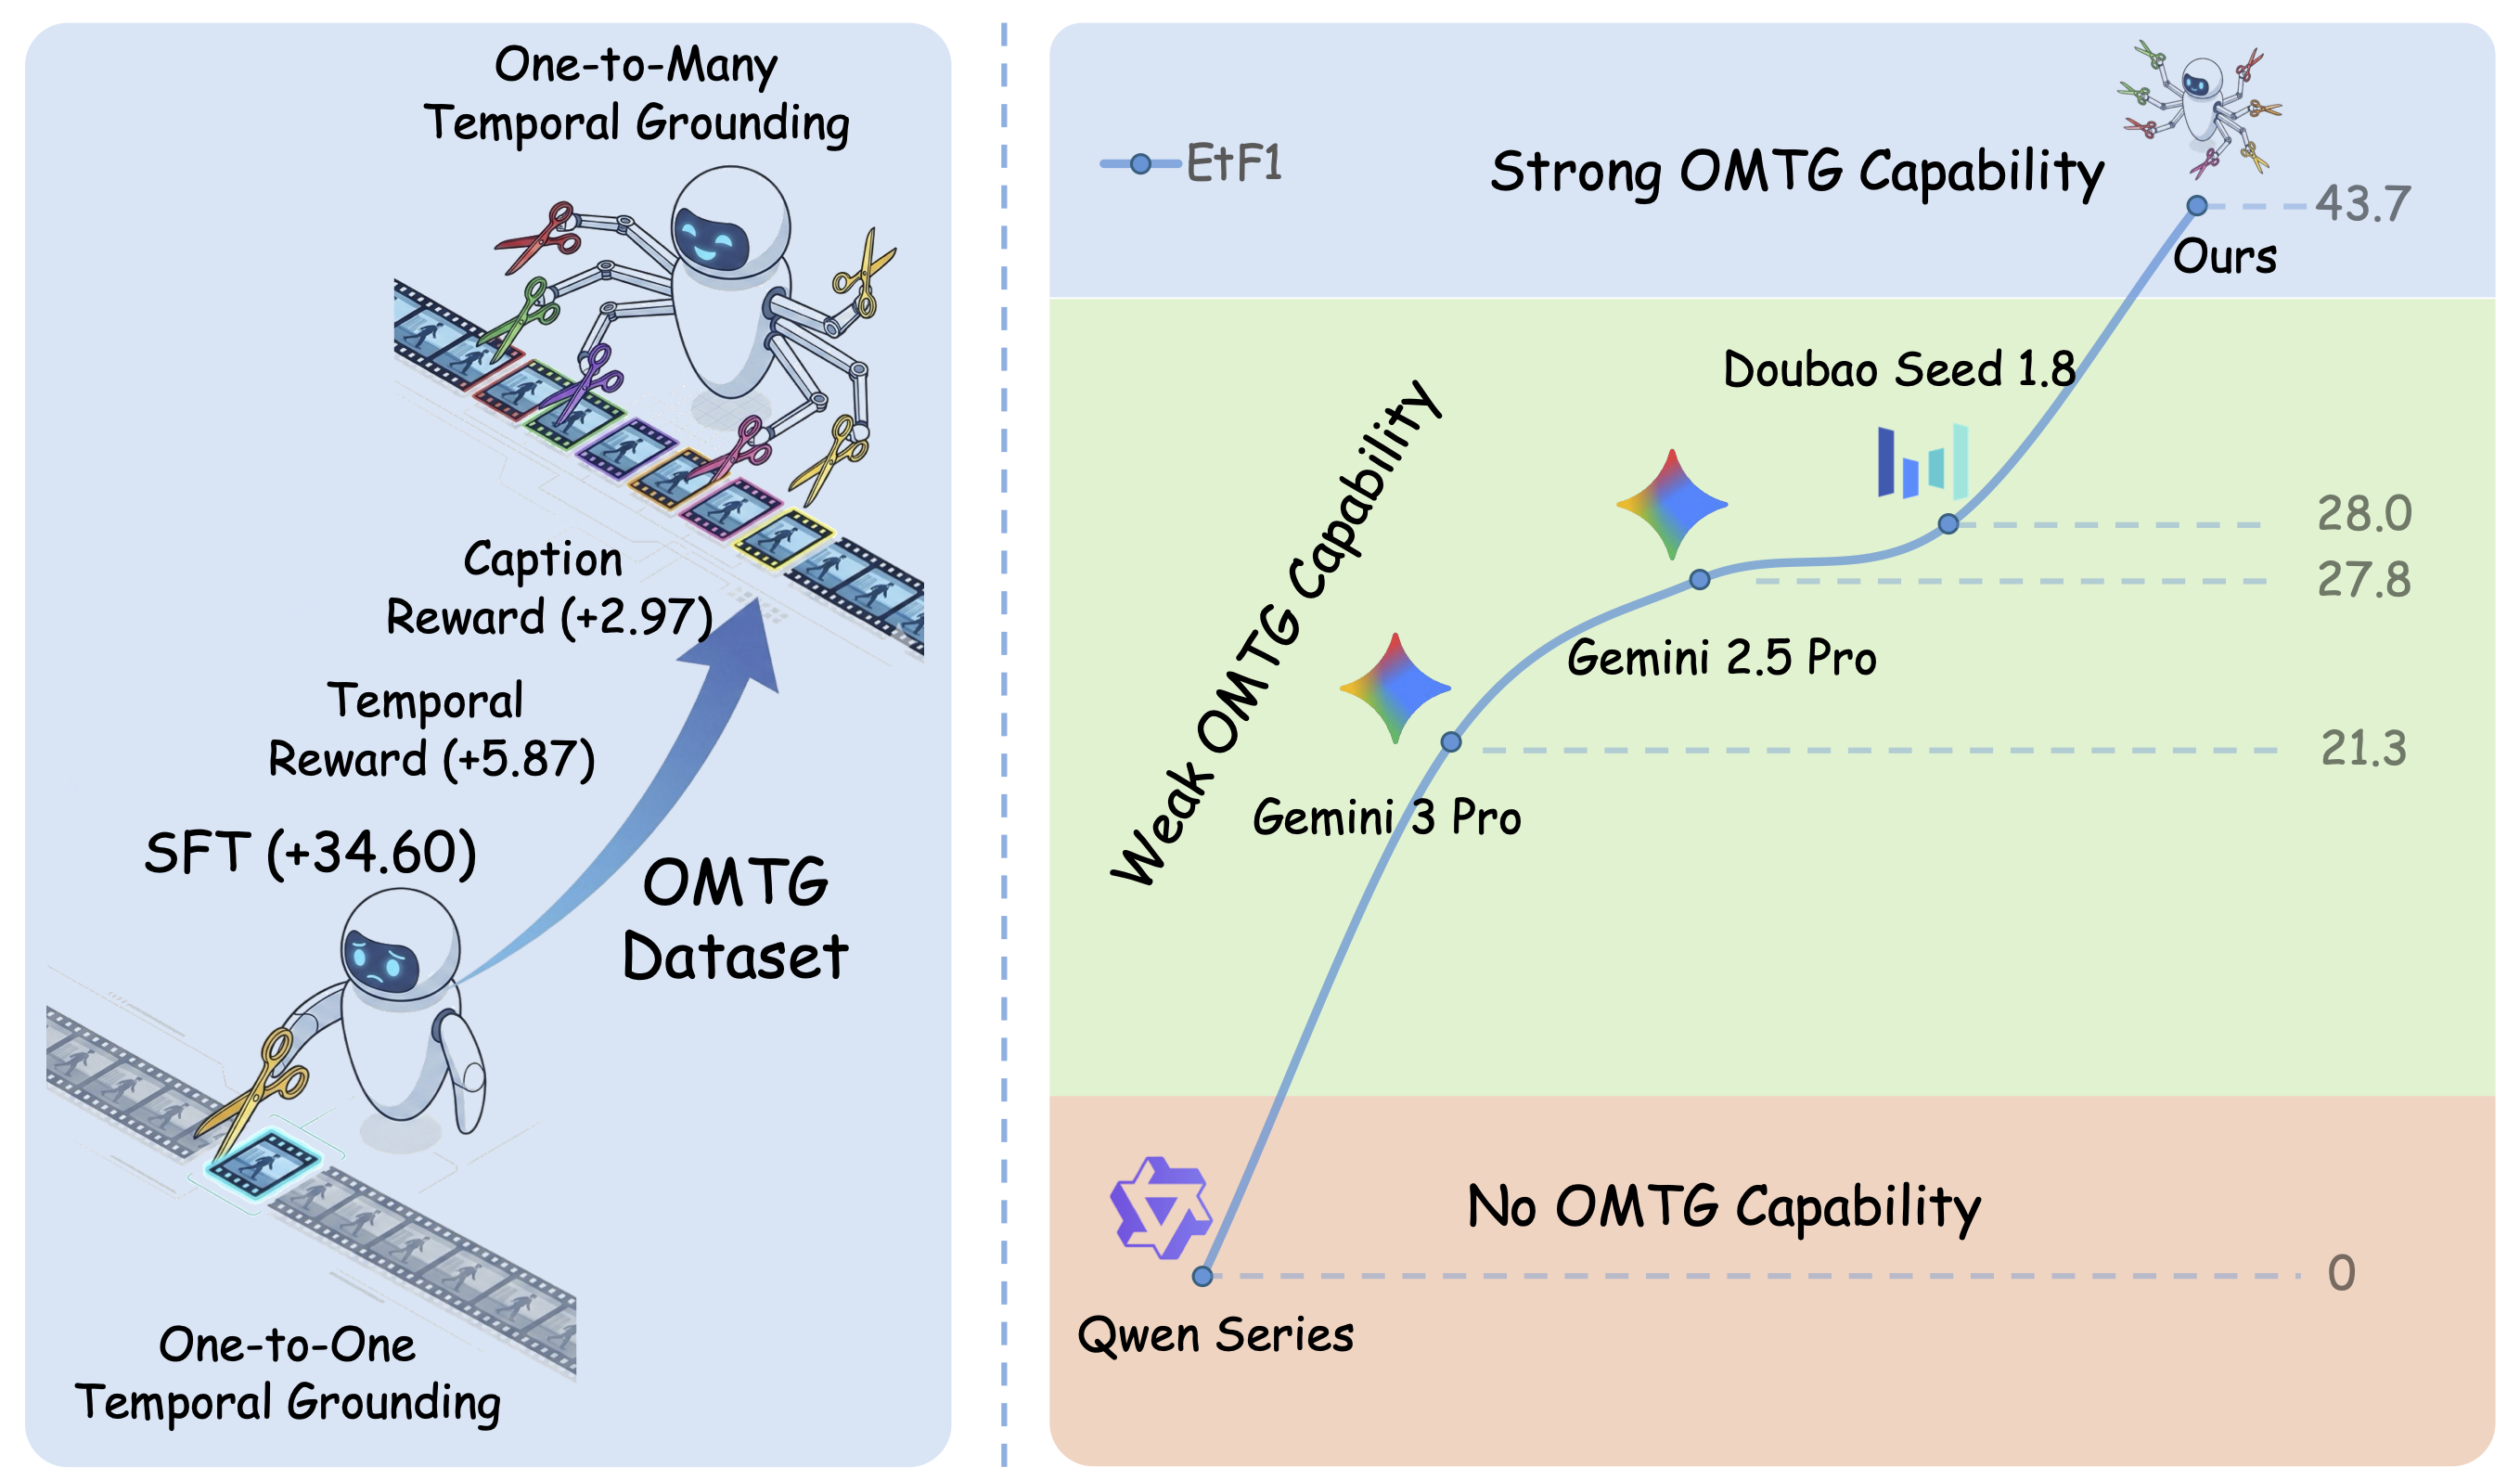
Towards One-to-Many Temporal Grounding was accepted to ICML 2026.
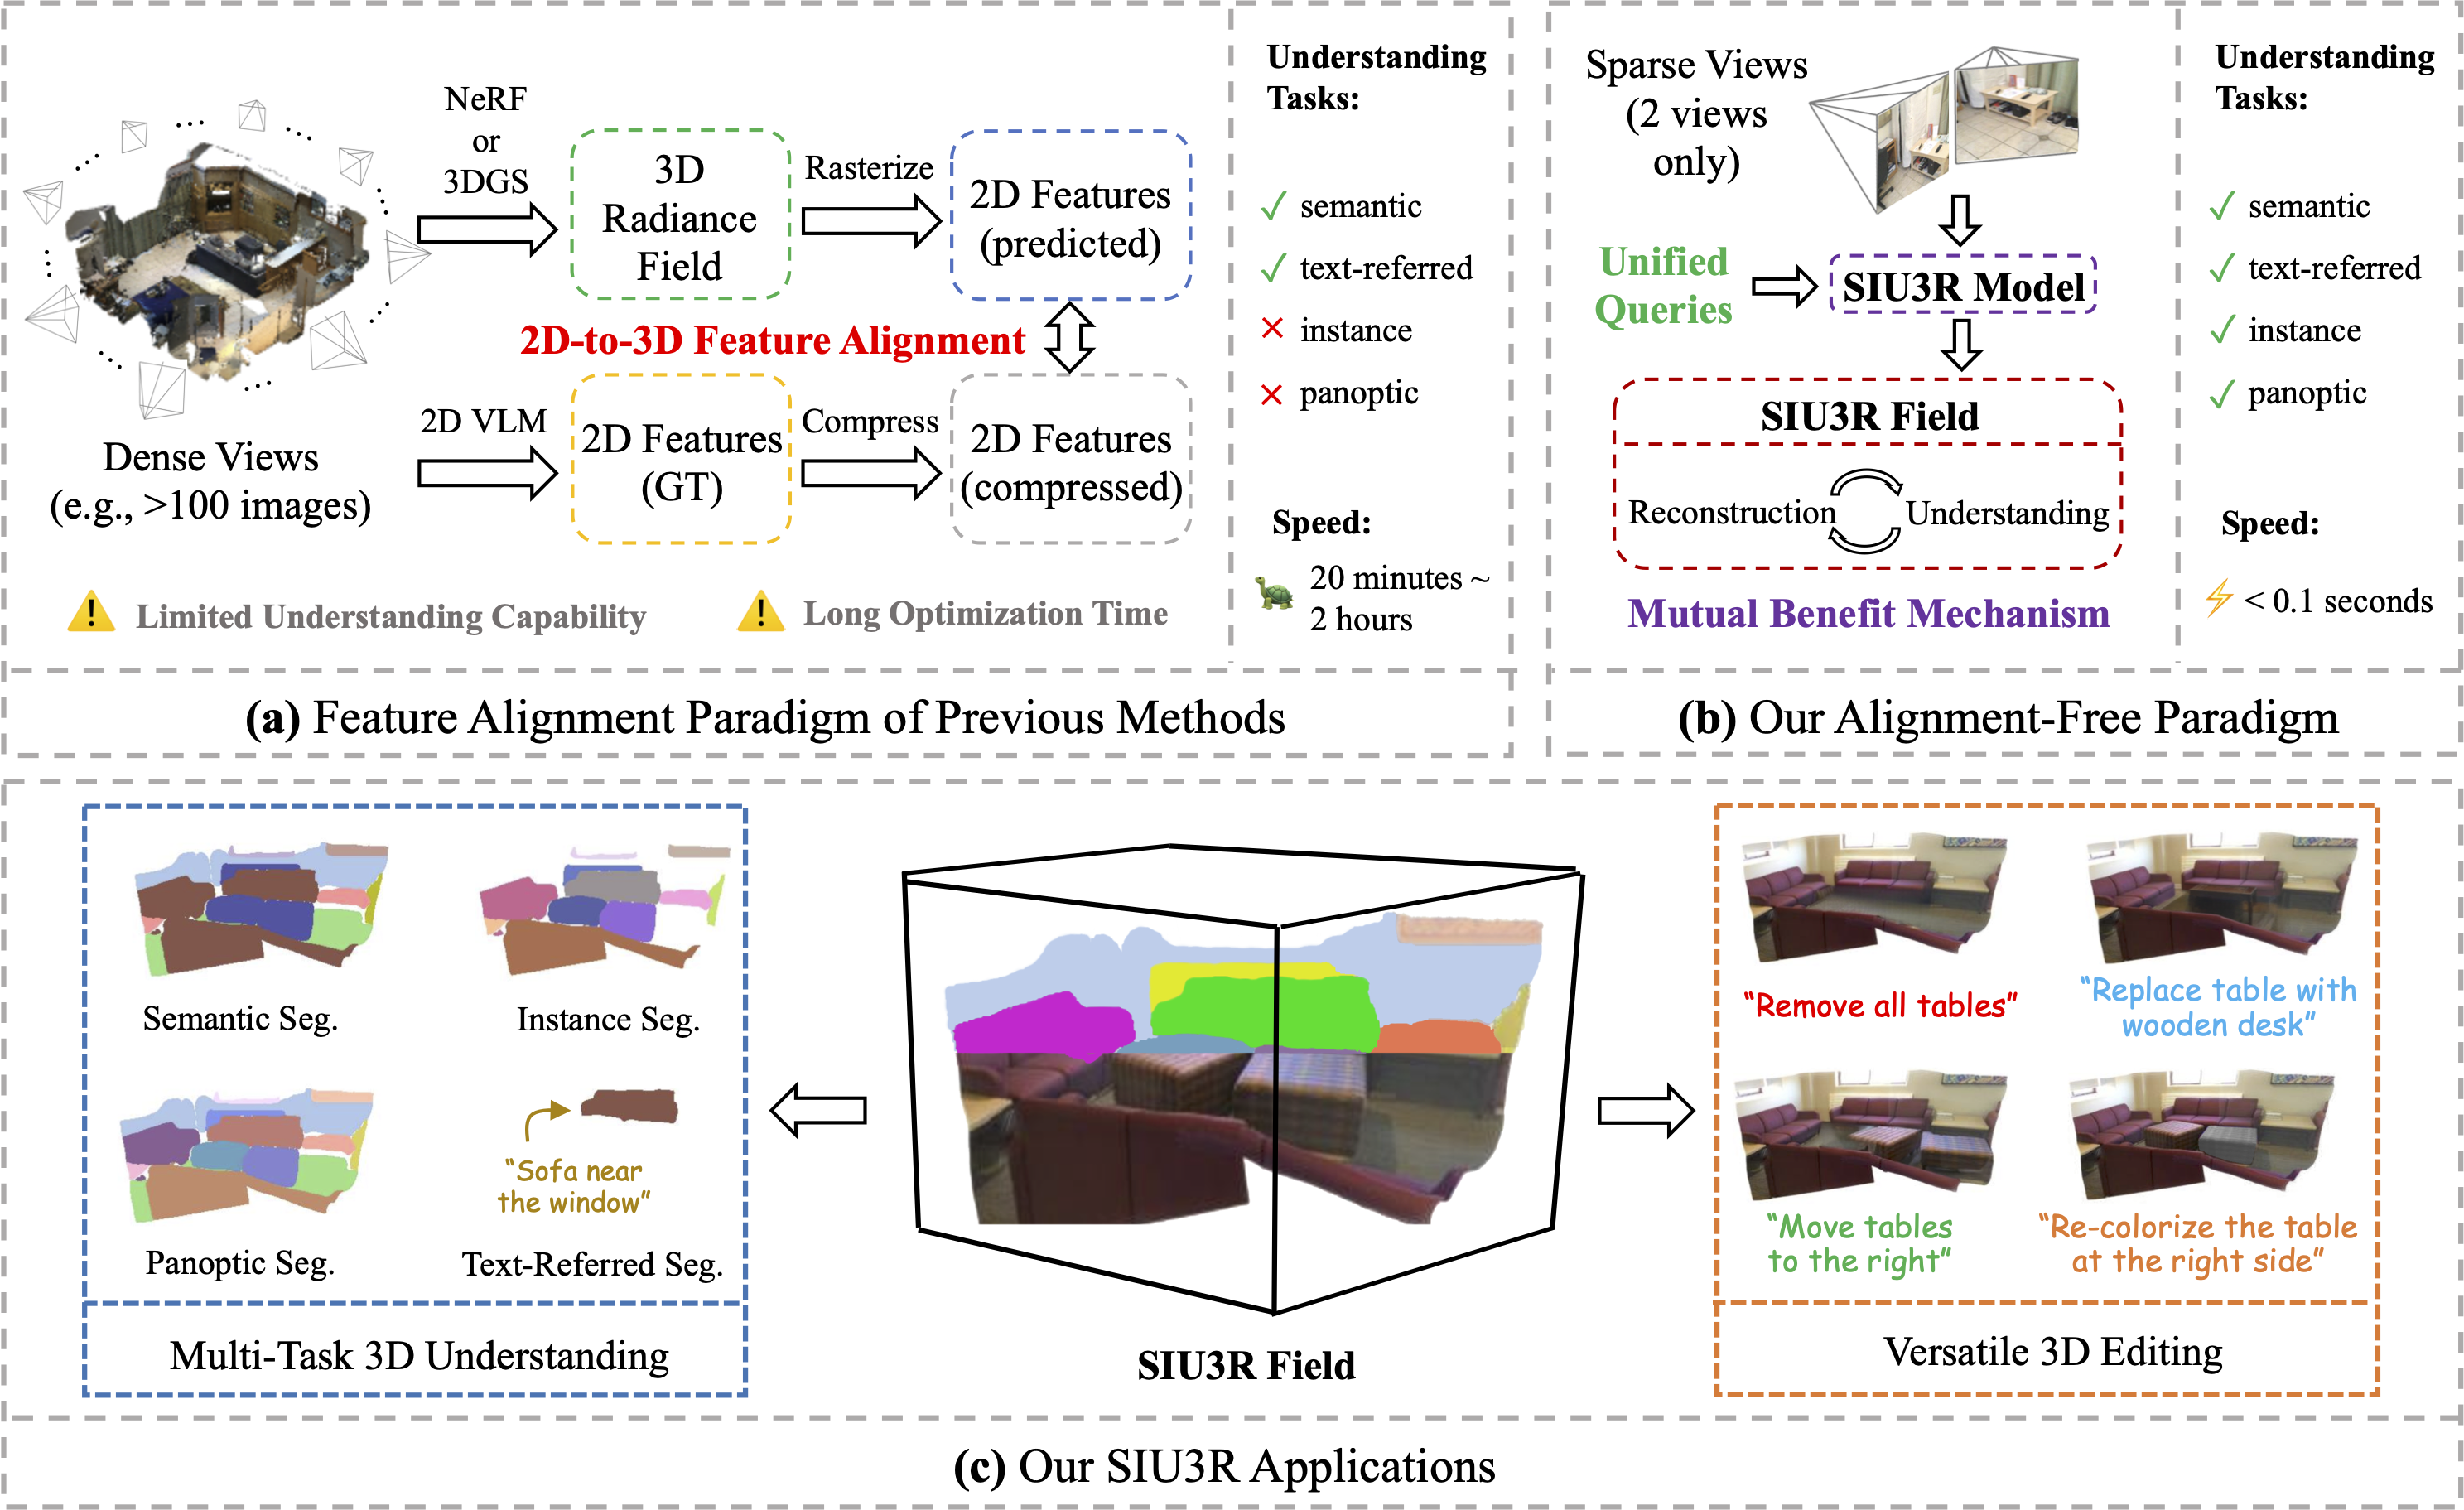
SIU3R received a NeurIPS 2025 Spotlight.
Qi Xu is underlined. * Equal contribution. † Corresponding author.
Reconstructs high-resolution 3D thermal scenes from low-resolution inputs via physics-informed degradation modeling.
A unified RGB-TIR reconstruction framework resolving cross-spectral visibility conflicts through thermal field modeling.
I am open to research conversations and collaborations on multimodal large language models, video understanding, spatio-temporal reasoning, and multimodal data and post-training.